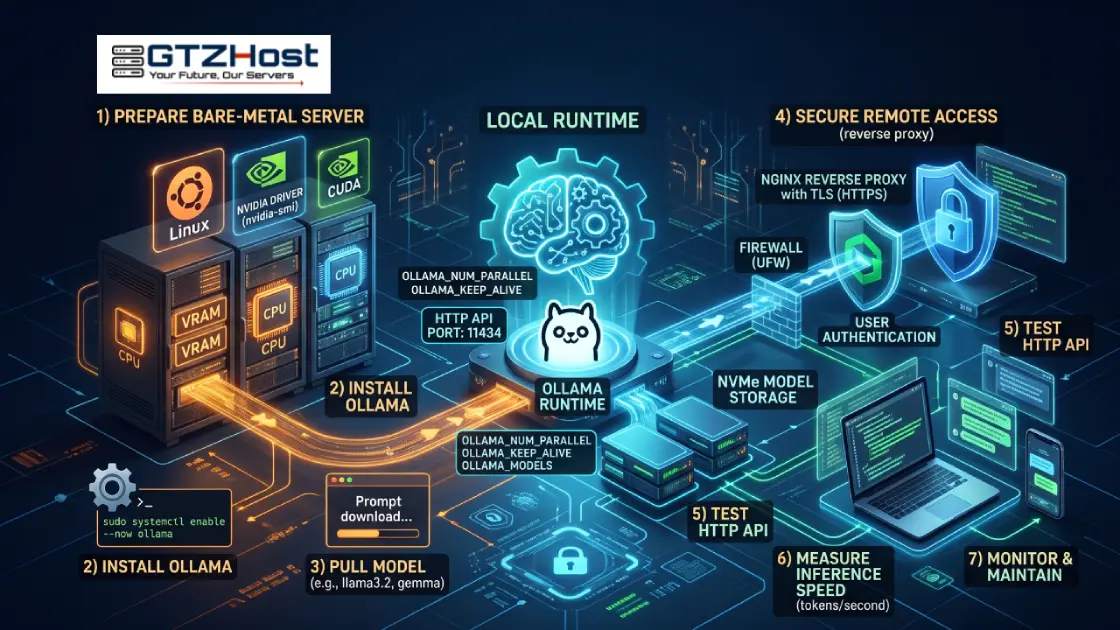
For enterprises migrating away from external LLM APIs to maintain data sovereignty, Ollama provides a streamlined, OpenAI-compatible HTTP daemon. However, moving from local experimentation to a production server requires specific architectural hardening and systemd tuning.
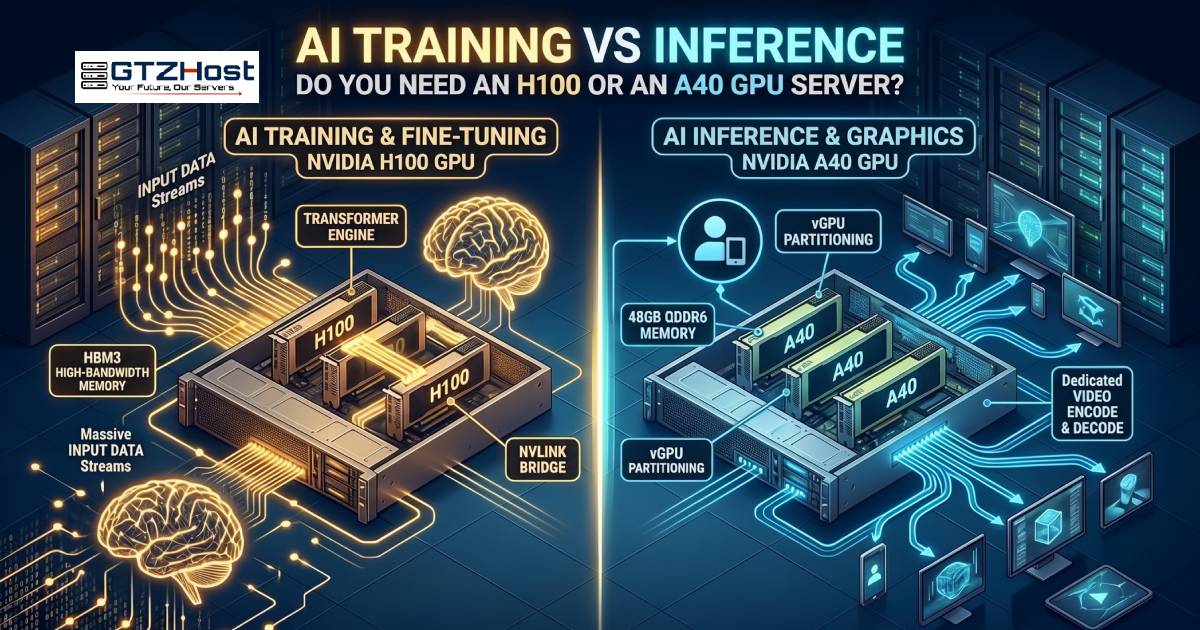
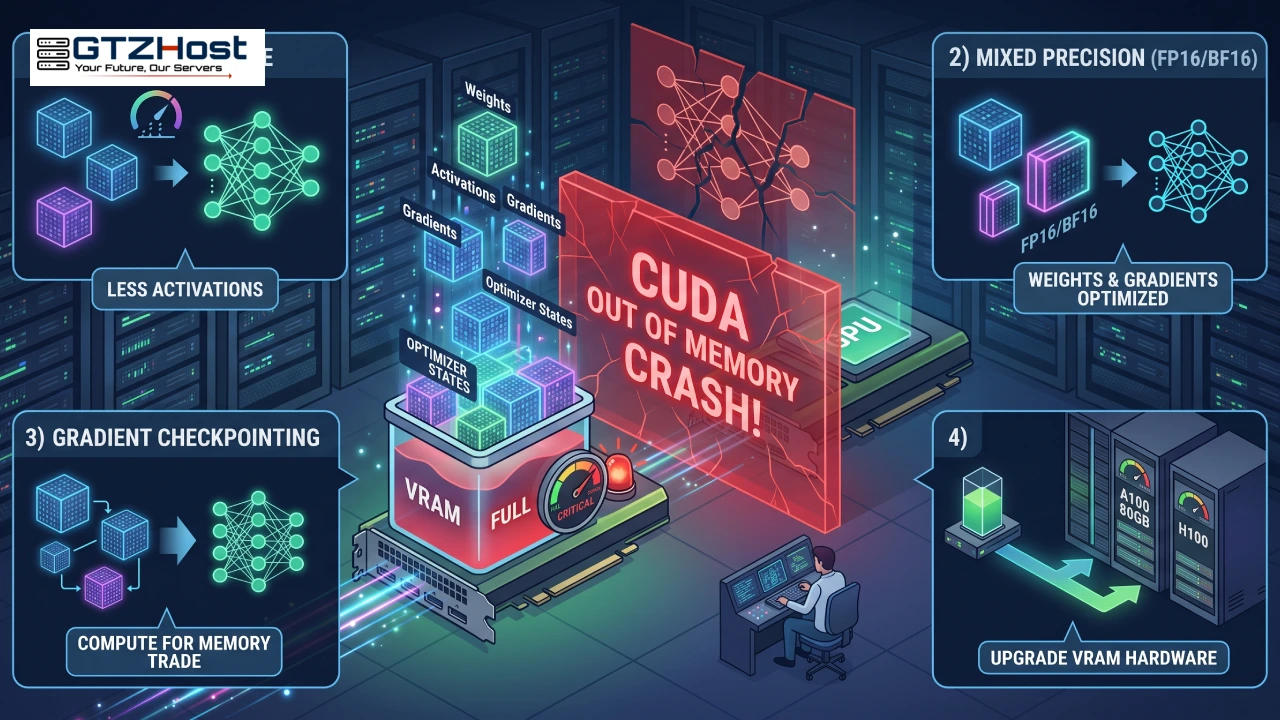
Daemon Configuration and VRAM Offloading Ollama automatically allocates tensor layers between the GPU and CPU based on available VRAM. You must monitor ollama ps to ensure 100% GPU utilization. If layers spill into system RAM, inference latency degrades exponentially. Ensure you provision gpu servers with adequate VRAM (e.g., NVIDIA A40 48GB or A100 80GB) to accommodate both the model weights and the context window (KV cache).
Nginx Reverse Proxy and Header Mutation Ollama lacks native authentication. Do not bind OLLAMA_HOST to 0.0.0.0. Bind it to localhost and utilize Nginx for TLS termination and Basic Auth. Ollama enforces strict Host header validation; if Nginx forwards the public domain name, Ollama returns 403 Forbidden. You must include proxy_set_header Host localhost:11434; in your Nginx configuration. Furthermore, disable proxy buffering (proxy_buffering off;) to support Server-Sent Events (SSE) for real-time token streaming.
Tuning Concurrency via Systemd By default, Ollama serializes requests. To enable concurrent inference, override the systemd daemon parameters by injecting OLLAMA_NUM_PARALLEL and OLLAMA_KEEP_ALIVE. Note that increasing parallelism linearly increases VRAM consumption due to isolated KV caches per request session.
Deploying these tuned configurations on bare-metal dedicated servers ensures your API maintains maximum hardware throughput and zero virtualization latency.
Read the complete command-line troubleshooting checklist and Nginx configuration files here:https://www.gtzhost.com/tutorials/howto/setup-local-llm-inference-server-ollama/
About the author
- High-performance AMD EPYC & Intel Xeon dedicated servers starting at $43/mo. Deploy across 250+ locations, including USA hubs like Missouri and Montana, to global nodes in Palermo. Your trusted global hosting provider.
Comments
Join the discussionNo comments yet. Be the first to comment.